# Product Pilot
AI copilot that generates PRDs, architecture docs, and success metrics from conversational input.
Status: active
## The Problem
Product documentation is the bottleneck between ideas and implementation. Writing a PRD takes hours of structured thinking — user stories, technical constraints, success metrics, edge cases. Most engineers skip it or produce thin specs that create ambiguity downstream. AI can generate text, but generic outputs lack the structured reasoning that makes a PRD actionable.
## What I Built
Product Pilot is a conversational interface that turns product thinking into a six-stage document set — Requirements Definition, North Star Brief, Design Requirements, Architecture & Technical Spec, Coding Prompts, and Development Guide — plus a newer adaptive-intake path that builds a typed spec (personas, needs, features, ADRs, API contracts, tests) and exports it as a single Markdown file a coding agent pastes directly.
The key differentiator is that the spec, not prose, is the source of truth. In the adaptive path, every document is rendered from one structured object rather than generated independently per section, so a Feature's `needIds` and a Test's back-references are real cross-references, not just consistent-sounding text. A deterministic + LLM linter checks the spec for contradictions and missing PII-handling notes before export, and findings travel with the export as advisories rather than blocking it.
## Architecture
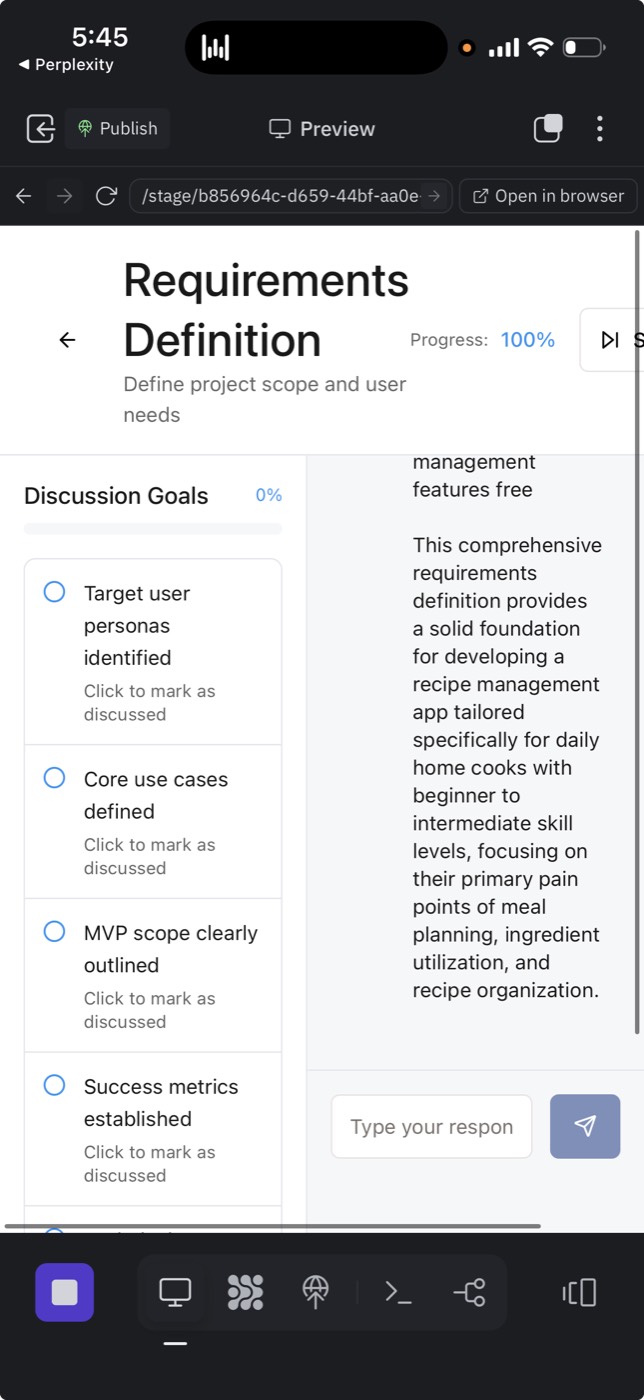
Two generation paths share one Express + Postgres backend:
- **Frontend** — React 18 + Vite 5 + Wouter (not Next.js) + Radix/shadcn, TanStack Query for data fetching.
- **Backend** — Express 4 on Node, deployed to Vercel as a dual build: a static Vite bundle plus an esbuild-bundled serverless function (`api/index.mjs`) that `/api/*` rewrites to.
- **Database** — Postgres (Neon), reached through `pg` + Drizzle ORM. Row-level security policies (hand-written SQL migrations, since drizzle-kit can't express `CREATE POLICY`) isolate `projects`, `stages`, `messages`, `intake_questions`, and `spec_artifacts` by actor — a signed-in user or a guest ownership token — at the database level.
- **Auth** — Better Auth with a Drizzle adapter, magic-link plugin, optional Google OAuth. (The repo's own README says "Neon Auth"; the code uses Better Auth — the code is the source of truth here.)
- **Models** — see table below; both a live default (Groq) and an Anthropic fallback/BYOK path exist, selected per task.
**Models — which, where, why:**
| Task tier | Model / where | Why |
|---|---|---|
| Deliverable / complex generation (live default, both keys set) | Groq `openai/gpt-oss-120b` | 2026-05-02 routing override: alpha intentionally runs on one live provider even with an Anthropic key present; ~4x cheaper than `llama-3.3-70b-versatile`, which the codebase keeps only as a costlier fallback alias, for comparable quality |
| Chat / classification (live default, both keys set) | Groq `llama-3.1-8b-instant` | 12x cheaper input than `llama-3.3-70b-versatile`; used for conversation and for the adaptive intake's sub-calls (method routing, blocking-score, progress %) |
| Complex tasks, Anthropic-only | Claude Opus | Selected only when `GROQ_API_KEY` is absent and an Anthropic key is present |
| Chat / deliverable, Anthropic-only or explicit BYOK | Claude Sonnet | Default Anthropic tier; also the structured-spec generation path (`generateStructuredOutputWithBlocks`), which uses `cache_control: ephemeral` system blocks and retries once on invalid JSON |
| Classification, Anthropic-only or explicit BYOK | Claude Haiku | Cheapest Anthropic tier for structured classification calls, including the two LLM-tier spec-linter checks (ambiguous language, unresolved contradiction) — these can only warn, never block; every `block`-severity lint issue comes from deterministic regex/structural rules |
⚠️ Not sourced in code: the README additionally lists "OpenAI (BYOK)." The `LLMConfig.provider` type and the `llm_calls.provider` DB column both carry `'openai'` as a value, but no OpenAI SDK is installed and neither `chat()` nor `generateStructuredOutput()` has an OpenAI branch — an `'openai'` config silently falls through to the Groq default. OpenAI is schema-modeled, not implemented, in this checkout.
**Tools & infra — which, why:**
- **PostgreSQL (Neon) + Drizzle ORM** — relational store for projects/stages/messages/spec artifacts; RLS enforces tenant isolation independent of app-layer checks, verified by a dedicated `test:rls` Vitest run (`RLS_SANDBOX=1`).
- **Better Auth + Resend** — session/JWT auth and optional transactional email for verification and magic-link delivery.
- **Sentry + pino** — error reporting and structured JSON logging.
- **Vercel** — hosting for both the static frontend and the Express API as a single serverless function (60s max duration).
- **drizzle-kit** — schema push (`db:push`); RLS policies and cross-schema FKs live in three hand-written SQL migration files because drizzle-kit has no abstraction for `ENABLE ROW LEVEL SECURITY` or `CREATE POLICY`.
- **Vitest** — unit/integration tests across intake scoring, spec-linter rules, agent-handoff rendering, and RLS policy behavior.
```mermaid
flowchart LR
subgraph Intake["Adaptive intake — one question at a time"]
A[User answer] --> B["IntakeController.nextStep
methodRouter + blockingScorer
(classification tier)"]
B -->|score >= 6| C[Ask: JTBD / QFD / Pugh / Agent question]
B -->|score < 6| D[Infer labeled-assumption default]
C --> E[ingestAnswer]
D --> E
E -->|scrubSecretsDeep| F[(productState JSONB
Postgres, RLS)]
F --> B
end
B -->|sufficiency gate hit| G["finalize()
productState -> Spec JSON
(deterministic, no LLM)"]
G --> H["spec-renderer
Spec -> Markdown, pure fns"]
G --> I["spec-linter
regex rules + Haiku/llama-3.1-8b-instant ambiguity check"]
I --> J[scrubSecretsDeep]
J --> K["generateHandoff()
agent-handoff.md
cache-friendly section order"]
H --> L[(spec_artifacts
Postgres, RLS)]
K --> M[Paste into Claude Code / Cursor / Codex]
subgraph Legacy["6-stage chat path (survey / minimum-details entry)"]
N["Stage 1-6 chat
Requirements Definition -> Dev Guide"] --> O["per-stage generation
deliverable/complex tier"]
O --> P[(messages, kind=deliverable
versioned)]
end
```
## How it works
1. The client posts to `/api/projects/:id/intake/answer`; `loadOwnedProject` resolves the request against Postgres RLS for the calling user or guest actor before anything else runs.
2. `IntakeController.nextStep` evaluates `productState` against classification-tier sub-prompts: `methodRouter` picks JTBD, QFD, Pugh, or an agent-system method; `blockingScorer` scores each candidate unknown 0–15 — ≥6 asks one question, below that infers a labeled-assumption default.
3. Every `productState` fragment is passed through `scrubSecretsDeep` before it reaches a model provider, so BYOK keys and secret-shaped strings never appear in a prompt.
4. `ingestAnswer` writes the answer to `intake_questions` and merges it into `productState` (stored as JSONB on `projects`).
5. Once the controller signals `done`, `/intake/finalize` calls `finalize()` — a pure, deterministic function that converts `productState` into a typed `Spec` (personas, needs, features, ADRs, data points, tests) and renders it to Markdown via `spec-renderer`'s pure functions. No LLM call happens in this step.
6. `/handoff.md` re-derives the same `Spec`, then runs `spec-linter`: a deterministic regex/structural pass (per-platform test-framework checks, non-waivable PII-without-handling-note rule) plus two Haiku/gpt-oss-tier LLM checks that can warn but never block.
7. Lint findings are advisory, not gating, by design (a "no-blocks" route comment dated 2026-05-08) — the export ships with unwaived warnings attached rather than being refused.
8. The `Spec` and `productState` are scrubbed once more at the boundary, then `generateHandoff()` assembles `agent-handoff.md` with prompt-cache-friendly section order — stable identity and stance first, dynamic needs/risks last — so a re-paste after edits keeps the leading prefix, and Anthropic's prompt cache, intact.
9. In parallel, a six-stage chat path exists for projects that entered through the older survey/minimum-details intake: each of the six fixed stages runs its own `generate-docs-from-survey` call on the deliverable/complex model tier, storing a versioned Markdown deliverable per stage, downloadable individually or concatenated via `/documents.md`.
10. Every provider call — chat, streaming, structured-output — records to `llm_calls` (provider, model, task, token counts, latency, cost computed from a static per-model rate table) feeding the admin cost-telemetry views.
## Tech stack
React 18 + Vite 5 + Wouter on the frontend, Express 4 on Node for the backend, deployed to Vercel as a static bundle plus one esbuild-bundled serverless function. PostgreSQL (Neon) via Drizzle ORM, with hand-written SQL migrations for row-level security policies drizzle-kit can't express. Better Auth (Drizzle adapter, magic link, optional Google OAuth) for sessions; Resend for transactional email. Two LLM providers: Groq (`openai/gpt-oss-120b` for reasoning/deliverables, `llama-3.1-8b-instant` for chat/classification) as the live default, Anthropic Claude (Opus/Sonnet/Haiku tiers) as the fallback path and the structured-spec-generation path, selected via `LLMTask`-based routing in `server/services/ai.ts`. Sentry + pino for observability, Vitest for tests including a dedicated RLS-policy suite.
## Links
- [HTML project page](https://rosslabs.ai/projects/product-pilot/)
- [Live app](https://productpilot-puce.vercel.app)
- [Source code](https://github.com/tyroneross/ProductPilot)