# Local Smartz
Ports Stratagem's research patterns to run entirely on local hardware — one DeepAgent, 8 custom tools, no cloud LLM — via web UI, CLI, or a native macOS app.
Status: active
## The Problem
Cloud LLM APIs are great until they're not — privacy-sensitive research, air-gapped environments, or just a desire to control the bill. Most agent frameworks assume an OpenAI-shaped API and fail interestingly when you point them at a local model. Smaller local models also break in different ways than frontier ones: silent tool-call drops, stringified JSON arguments, and runaway loops on ambiguous prompts.
## What I Built
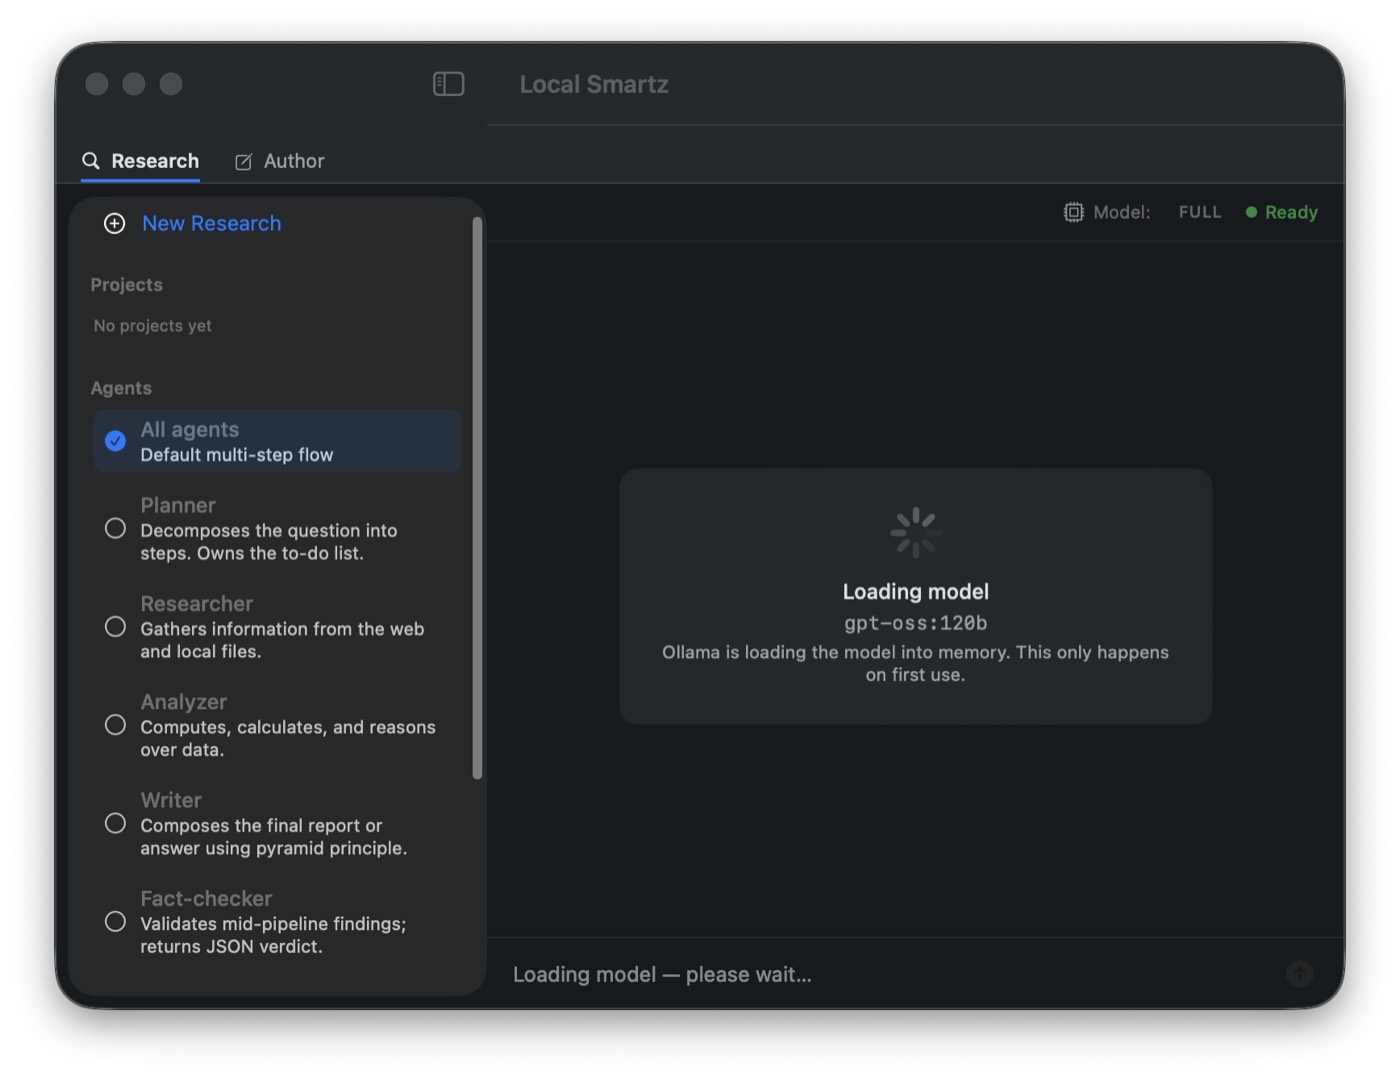
A local-first port of the multi-agent research patterns from Stratagem. Single DeepAgent (LangChain / LangGraph) handles orchestration with built-in `write_todos` planning, subagent spawning via the `task` tool, and filesystem-based context offloading. Eight custom tools cover web search, page scraping, PDF/spreadsheet/text parsing, sandboxed Python execution, and report/spreadsheet generation.
## Architecture
Every query enters through one router (`routing.select_research_runtime`) that reads the prompt text and picks one of five execution paths — no LLM makes this decision, it's regex/keyword matching against the prompt. The default research path is a deterministic LangGraph state machine (`pipeline.py`), not a free-form agent loop: researcher and analyzer run in parallel, a fact-checker gates the output, and re-dispatch is bounded at 2 iterations. This replaced an earlier prompt-driven DeepAgents orchestrator specifically because small local models (qwen3:8b) forgot to emit parallel `task()` calls or ignored the fact-checker's verdict — encoding those steps as graph edges instead of instructions removed that failure mode.
```mermaid
flowchart TD
A[CLI / REPL / Web UI / macOS app] --> B{Router
routing.select_research_runtime}
B -->|trivial factual prompt| C["Fast path
fast_model, no tools, no graph"]
B -->|repo/build-loop/plugin prompt| D["Coding harness / coding loop
repo-grounded, action-oriented"]
B -->|focus_agent pinned| E["Legacy DeepAgents runtime
single agent + task() delegation"]
B -->|default research query| F[Entry node]
F -->|Send, parallel| G[Researcher
web_search, scrape_url, parse_pdf]
F -->|Send, parallel| H[Analyzer
python_exec]
G --> I[Fact-checker
JSON verdict: ok / needs_more]
H --> I
I -->|needs_more, iters < 2| G
I -->|ok, or iters exhausted| J[Writer
pyramid-principle synthesis]
J --> K[SSE stream to caller]
K --> L[(SQLite checkpointer
threads + messages.jsonl)]
```
### End-to-end data flow
1. **Entry** — a query arrives via CLI (`localsmartz "..."`), REPL, the SSE-streaming HTTP server (`--serve`, stdlib `http.server` on port 11435), or the SwiftUI macOS app (subprocess-launches the Python backend, streams via `URLSession.bytes`).
2. **Routing** — `routing.select_research_runtime` classifies the prompt: trivial factual questions ("what is...", under 400 chars) go to a fast path that skips the graph entirely; prompts naming a repo/build-loop/plugin path go to a coding harness (read-only repo context) or coding loop (action-oriented); everything else enters the graph pipeline (default since 2026-04-13, `LOCALSMARTZ_PIPELINE` env var opts back to the legacy path).
3. **Fan-out** — the graph's `entry` node dispatches `researcher` and `analyzer` in parallel via LangGraph's `Send`. Researcher calls `web_search` (DuckDuckGo via `ddgs`) then `scrape_url`/`parse_pdf`/`read_spreadsheet` on the best results. Analyzer runs `python_exec` for any math the query needs — it has no access to researcher's output (true parallel branch, no shared disk state).
4. **Verification** — both outputs converge on `fact_checker`, which re-verifies uncertain claims with `web_search`/`scrape_url` and returns a strict JSON verdict (`{"verdict": "ok"|"needs_more", "missing_facts": [...]}`). `needs_more` re-dispatches `researcher` with the named gaps, capped at 2 extra rounds — after that the graph writes with whatever it has rather than spin indefinitely.
5. **Synthesis** — `writer` composes the final answer using pyramid-principle structure (governing thought, then 2–4 MECE key lines, then support), pulling only from the researcher/analyzer outputs already in state — it runs no new searches.
6. **Output & persistence** — the answer streams to the caller over SSE, token-by-token. `threads.py` persists the exchange to `.localsmartz/threads/{thread_id}/messages.jsonl` plus an auto-generated `context.md` summary (loaded back into the system prompt on thread resume); `artifacts.py` tracks every generated file (report, spreadsheet) in an index. A SQLite-backed `SqliteSaver` (`langgraph-checkpoint-sqlite`) checkpoints agent state so a thread survives a backend restart.
### Models — which, where, why
All inference is local via Ollama by default; no cloud API key is required to run the app.
| Profile | Role(s) | Model | Why here |
|---------|---------|-------|----------|
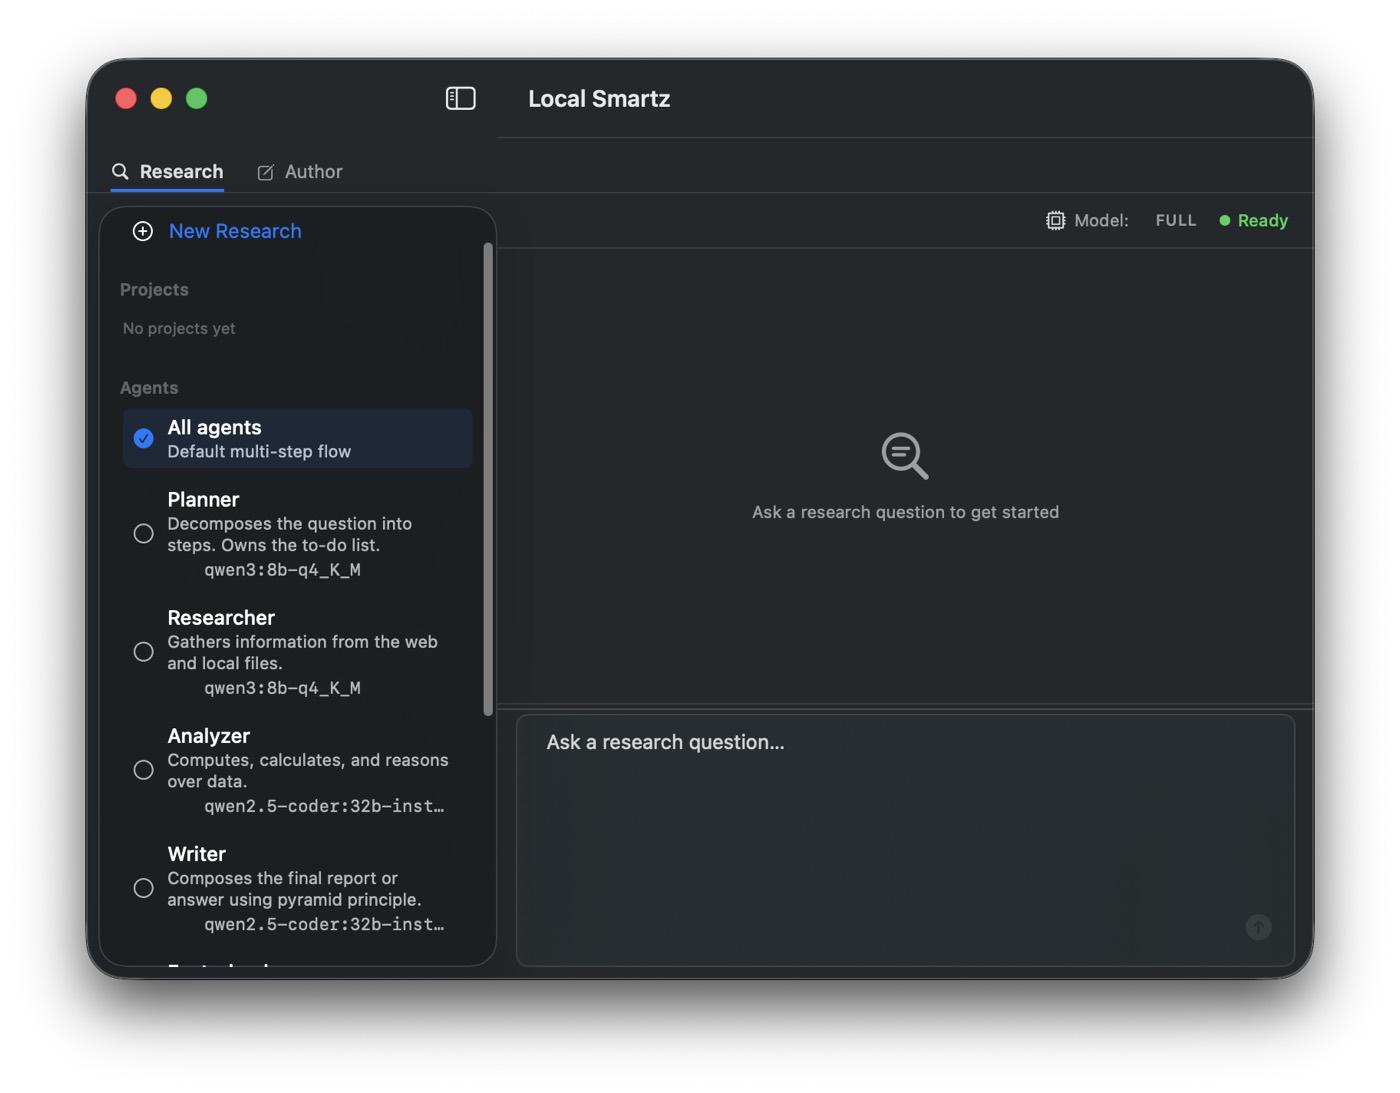
| **full** (≥64 GB RAM) | planner, researcher, writer, fact_checker, orchestrator | `gpt-oss:20b` | Tool/agent-oriented model, lighter than gpt-oss:120b — used everywhere except the compute-heavy analyzer role |
| **full** | analyzer / execution | `qwen2.5-coder:32b` | Code-and-math-specialized model reserved for the one role that runs arbitrary Python |
| **full & lite** | fast path (trivial factual prompts) | `qwen3:8b-q4_K_M` | Keeps first-token latency low for one-line answers by never loading the 20B/32B models |
| **lite** (<64 GB RAM) | every role (planner/researcher/analyzer/writer, no fact-checker, no subagent delegation) | `qwen3:8b-q4_K_M` | Single 8B model fits a 20 GB M4 with room to spare; the profile also swaps in a stricter one-tool-per-turn system prompt, a 5-tool whitelist, a 10-turn cap, and a loop detector — mitigations for the specific failure modes small local models exhibit (tool-name hallucination, stringified JSON args, runaway loops) rather than trusting a bigger prompt to prevent them |
Hardware profile is auto-detected from system RAM (`sysctl hw.memsize` on macOS) at ≥64 GB → full, else lite; overridable with `--profile lite`.
**Cloud fallback (opt-in, off by default).** A "Local-Only" setting gates cloud providers — when it's on (default, and fail-closed if the config can't be read), any non-Ollama provider is blocked outright. When a user explicitly enables a cloud provider, `routing.py`'s tier table maps each role to cheap/mid/strong and picks a concrete model per provider: Anthropic (`claude-haiku-4` / `claude-sonnet-4-6` / `claude-opus-4-7`), OpenAI (`gpt-4o-mini` / `gpt-4o`), Groq (`llama-3.1-8b-instant` / `llama-3.3-70b-versatile` / `openai/gpt-oss-120b`). This is a manual escape hatch for users who want cloud-quality synthesis, not a default routing signal — the project's premise is that inference never has to leave the machine.
### Tools & infra
| Component | Choice | Why |
|-----------|--------|-----|
| Orchestration | LangGraph (`StateGraph`, `Send`) + DeepAgents (legacy path) | Deterministic graph edges replace LLM-decided control flow for the failure modes small local models hit (missed parallel dispatch, ignored verdicts) |
| LLM runtime | Ollama via `langchain-ollama` (`ChatOllama`), not the OpenAI-compat shim | The OpenAI-compatibility layer silently drops tool calls in streaming mode; `langchain-ollama` keeps the tool-call channel intact |
| Checkpointing | SQLite (`langgraph-checkpoint-sqlite`, one `checkpoints.db` per project) | Threads resume across process restarts without an external database — matches the local-first, single-user scope |
| Thread/artifact store | Flat files: `messages.jsonl` + `context.md` per thread, `artifacts/index.json` | Ported from a prior project (Stratagem); no DB needed for a per-project, single-user append log |
| Web search | `ddgs` (DuckDuckGo) | No API key required — keeps the zero-cloud-dependency story intact for the research tool itself |
| Scraping / documents | `beautifulsoup4` + `lxml`, `pypdf`/`pdfplumber`, `openpyxl`, `python-docx` | Standard, dependency-light parsers for the source formats research tasks actually hit |
| Sandboxed compute | `python_exec` — subprocess `python3` call, 30s timeout, script saved to `.localsmartz/scripts/` for audit | Every numeric answer must flow through here, never LLM-generated arithmetic — local models hallucinate math reliably |
| Observability | OpenTelemetry → OTLP/HTTP → local Arize Phoenix collector (`localhost:6006`) | Opt-in (`--observe`, dev dependency group) so the base install stays light; traces every tool call and model turn without a hosted telemetry bill |
| Secrets | `keyring` (macOS Keychain / Linux secret-tool / file fallback) | Only path that touches secret storage — cloud provider API keys, when a user opts in |
| Web/desktop surface | stdlib `http.server` (no framework) + SSE, SwiftUI macOS app (`NavigationSplitView`, `MenuBarExtra`, `URLSession.bytes` for streaming) | Zero extra server dependency for the bundled DMG; native macOS chrome without a second backend |
## Tech stack
Python 3.12, Ollama (`gpt-oss:20b` planning/writer/researcher/fact-checker, `qwen2.5-coder:32b` analyzer, `qwen3:8b-q4_K_M` lite-profile and fast-path), DeepAgents + LangChain + LangGraph (`StateGraph`/`Send` deterministic pipeline), `langgraph-checkpoint-sqlite` (thread checkpointing), `ddgs` (web search), BeautifulSoup/lxml + pypdf/pdfplumber + openpyxl + python-docx (scraping and document parsing), OpenTelemetry + Arize Phoenix (opt-in local tracing), `keyring` (secret storage), stdlib `http.server` + SSE (web UI/API), SwiftUI (macOS app). Cloud fallback, off by default: Anthropic / OpenAI / Groq via `langchain-anthropic` and `langchain-openai`.
## Surfaces
- **CLI** — `localsmartz "question"`, interactive REPL, `--thread ` for resumable research, `--list-threads`
- **HTTP server** — `localsmartz --serve` runs an SSE-streaming server on `127.0.0.1:11435` (stdlib `http.server`, no extra deps)
- **macOS app** — SwiftUI wrapper around the Python backend. NavigationSplitView for thread history, streaming output, MenuBarExtra. Subprocess-launched backend, SSE streamed via `URLSession.bytes`. Builds via XcodeGen + Xcode 14+, ships as a DMG.
## Key Design Decisions
**Calculation policy is non-negotiable** — every numeric answer flows through `python_exec`, never LLM-generated arithmetic. Local models hallucinate numbers reliably.
**Sync tools, not async** — local models behave better with synchronous tool execution. The async-first patterns common in cloud frameworks introduce timing variability the local stack handles poorly.
**ChatOllama, not OpenAI compatibility shim** — the OpenAI-compat layer silently drops tool calls in streaming mode. `langchain-ollama` keeps the tool-call channel intact.
**Thread context + artifact manifest** — ported wholesale from Stratagem. `messages.jsonl` + `context.md` per thread, plus an artifact manifest tracking every generated output. Research is resumable across sessions.
**Resilient parameter parsing** — `create_report` and `create_spreadsheet` accept both list-of-dict and stringified JSON arguments. Local models stringify roughly 20% of structured tool calls; rather than fight that, parse both shapes.
## Results
⚠️ no benchmark yet — no throughput, accuracy, or task-completion numbers have been published for either hardware profile. What's on record from the build: two auto-detected profiles (full on a 128 GB Mac, lite on a 20 GB M4), an observed ~20% stringified-JSON rate on structured tool calls from local models (the reason `create_report`/`create_spreadsheet` parse both shapes), and a fixed 5-tool whitelist plus turn-cap for the lite profile's loop detector. No end-to-end research-run timing, cost, or output-quality measurements exist yet.
## Links
- [HTML project page](https://rosslabs.ai/projects/local-smartz/)
- [Source code](https://github.com/tyroneross/local-smartz)